
Codiatech Blog
TokenEconomizer and the Cost of Repeated Work in AI Coding
Microsoft Research’s TokenEconomizer uses repository experience to reduce repeated work. We examine the research, its limits and a practical pilot that measures cost alongside accepted output and review effort.
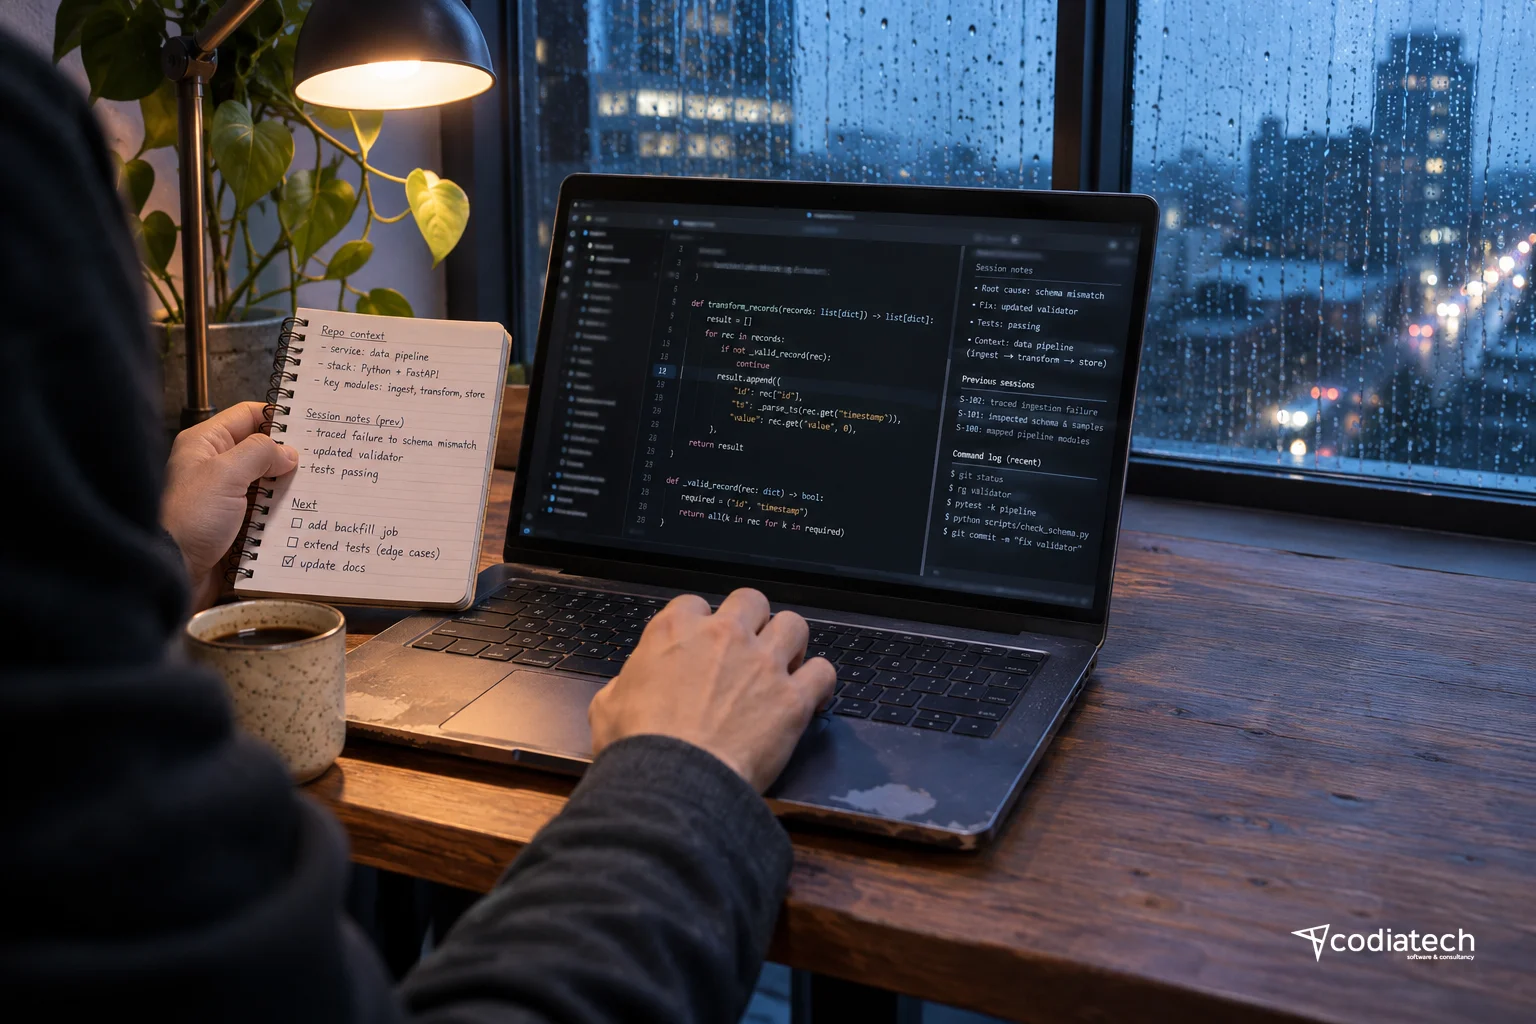
Why TokenEconomizer Matters to Software Teams
Microsoft Research introduced TokenEconomizer in a November 16, 2026 announcement. The open-source plugin learns from completed coding-agent sessions in a repository and uses that experience to reduce repeated work in later sessions. It operates alongside the existing agent without changing its underlying model. The project brings together UC Berkeley, Microsoft Research and Microsoft Security. Microsoft Research announcement
For a development team, the practical question starts with recurring work. When each maintenance task involves finding the test setup again, exploring familiar dependencies or revisiting an already understood error, that effort deserves measurement. A useful evaluation connects the cost of operating an agent with the quality of the change the team eventually accepts. Repository knowledge becomes part of that evaluation.
What the Reported Savings Mean
The evaluation covers 277 SWE-Bench tasks from six repositories and five agent-model combinations. It reports an 18.4–30.9% reduction in average cost. Those figures describe the study's tested conditions. They do not establish the savings a particular company will achieve in its own development budget. Results in the official repository
A team should assess successful delivery alongside model spending. A cheap run that fails acceptance checks still leaves the work unfinished. The change needs to pass relevant tests, satisfy the requested behaviour and survive review. Cost per accepted task is therefore a more useful pilot measure than the spending of an isolated session. Record failed attempts as part of the total effort required to complete the work.
Include the learning period in the comparison. The researchers explain that early tasks can cost more while experience accumulates. Selecting only the best later sessions would hide part of the adoption cost. Define the observation window before the pilot and keep all work inside it in the results, including the effort spent learning and checking the repository. The announcement's discussion of early tasks
How the Three Mechanisms Affect Daily Work
Short Notes About the Repository
Micro-skills capture repeatedly confirmed repository facts as brief notes. Teams should check that learned instructions continue to match their current environment. A useful pilot can deliberately change a test command and inspect what happens to the older instruction. Give reviewers a way to understand the evidence behind an important note and when it needs another check. A remembered setup instruction becomes less useful when the project has moved to a different workflow.
Reducing Unused Tool Definitions
Tool pruning aims to stop loading tools that previous sessions did not use. Restoring removed tools is part of the project's described behaviour. During a pilot, verify that the agent can still perform the work the team needs, including tests, file changes, dependency inspection and browser validation where applicable. A new task may require a tool that earlier tasks never needed. Someone should be able to recognise that situation and restore access.
Redirecting Repeated Failures
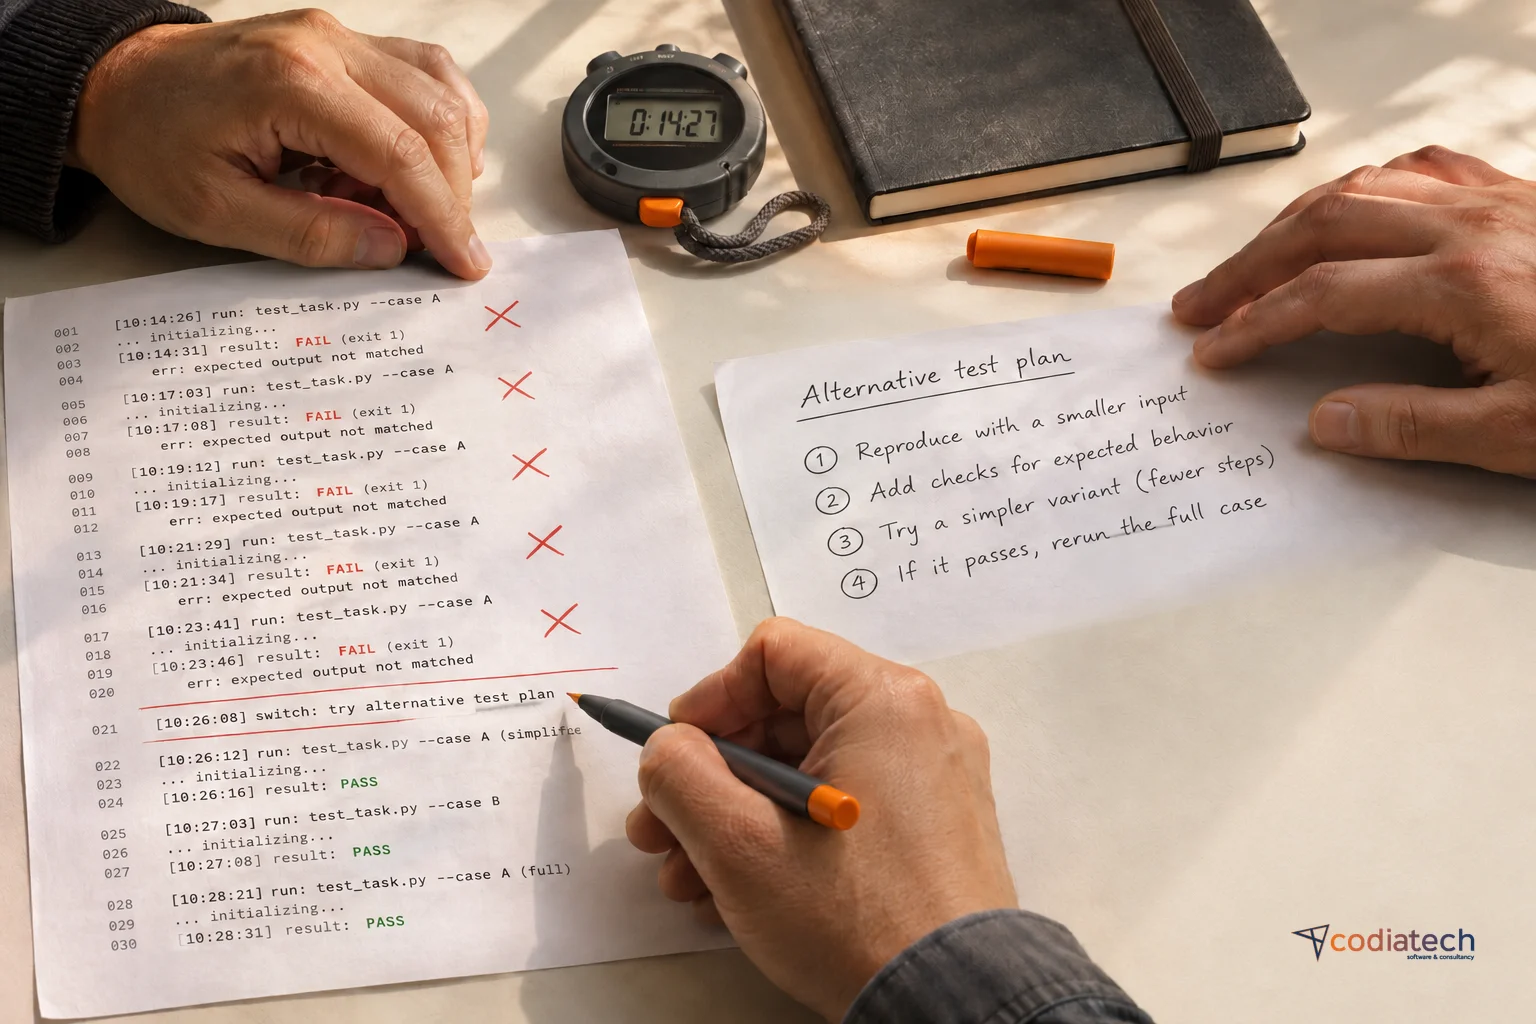
Failure-loop intervention suggests a different approach when an agent becomes stuck. The project says the plugin does not stop the work itself. A controlled task with a recurring error can test whether the resulting guidance leads to a valid, tested fix. Counting fewer attempts alone would miss the quality of the final result. These three mechanisms are documented in the project repository. How TokenEconomizer works
Which Teams Could Evaluate It First?
Codiatech's assessment is that teams regularly maintaining the same repository have a sensible starting point for a small pilot. In a rapidly changing project, first consider how long learned information remains useful. In a repository visited only occasionally, setup and review effort may carry a different weight. Write down the types of repeated work the team actually encounters so the evaluation can address a concrete operational question.
For example, a corporate application could provide a task group containing an API bug fix, an interface change and a test repair. Each task would need a defined outcome and a comparable level of difficulty. Keep permissions and tool availability consistent across the comparison. This is an illustrative pilot design, rather than a report of a Codiatech customer deployment or a measured customer result.
What to Measure in a Pilot
Start with a baseline. Record the model, agent version, available tools, cache pricing, task scope and acceptance checks. A change in the model or its pricing during the comparison makes it harder to attribute a result to the plugin. Examine the mix of work as well. Treating a small bug fix and a substantial module change as interchangeable tasks can make an average look more informative than it is.
- Track total model cost per accepted task, including learning and auxiliary evaluation calls.
- Record success using automated tests, task acceptance criteria and human review.
- Measure developer review and rework time alongside elapsed task time.
- Log repeated failed commands, outdated notes and tools that needed to be restored.
Agree on continuation and stopping criteria before the pilot begins. Test how the team returns to its normal workflow if it disables the plugin. Break results down by task type so a single percentage does not conceal an expensive category of work. With a small sample, describe the result as a direction for further evaluation and keep the uncertainty visible in the adoption decision.
Session Logs and Company Data
The plugin uses previous session logs. Before a corporate pilot, establish which logs will be processed and what project information they contain. If logs may include customer data, access details or production output, limit the evaluation accordingly. Maintain organisational boundaries between customer repositories, accounts and learned information. The person evaluating an efficiency tool should understand the same data responsibilities as the person operating the underlying development agent.
Review local storage alongside the context sent to the model provider and access within the team. Check the data terms of the agent, provider and applicable company agreement. Assign responsibility for inspecting learned notes, choosing retention periods and handling the end of a project. These are Codiatech's recommendations for a corporate evaluation. They should be adapted to the actual environment, permissions and contract rather than treated as a product assurance.
Where Codiatech's Services Fit
TokenEconomizer gives AI-assisted development teams a concrete subject for an efficiency pilot. Codiatech's custom software development and AI-powered systems work can consider such an evaluation within the project's scope. Excess generated code, test coverage and maintenance effort can also be assessed through AI code cleanup.
The practical next step is to identify recurring work and measure cost, accepted output and review effort together on a small task group. Let evidence from the team's own repositories guide adoption. A published research range can inform questions for the experiment, while the decision should reflect the work the organisation actually needs to deliver. The source announcement is dated November 16 and this assessment was prepared on November 17, 2026.
Sources
Primary source: www.microsoft.com